Nvidia releases Nemotron 3.5 Super VL with a 1M-token context window
NVIDIA says the open-weight model activates just 12 billion of its 120 billion parameters per query, runs in NVFP4 format on one DGX Spark, and ships alongside two smaller Bolt models for edge devices.
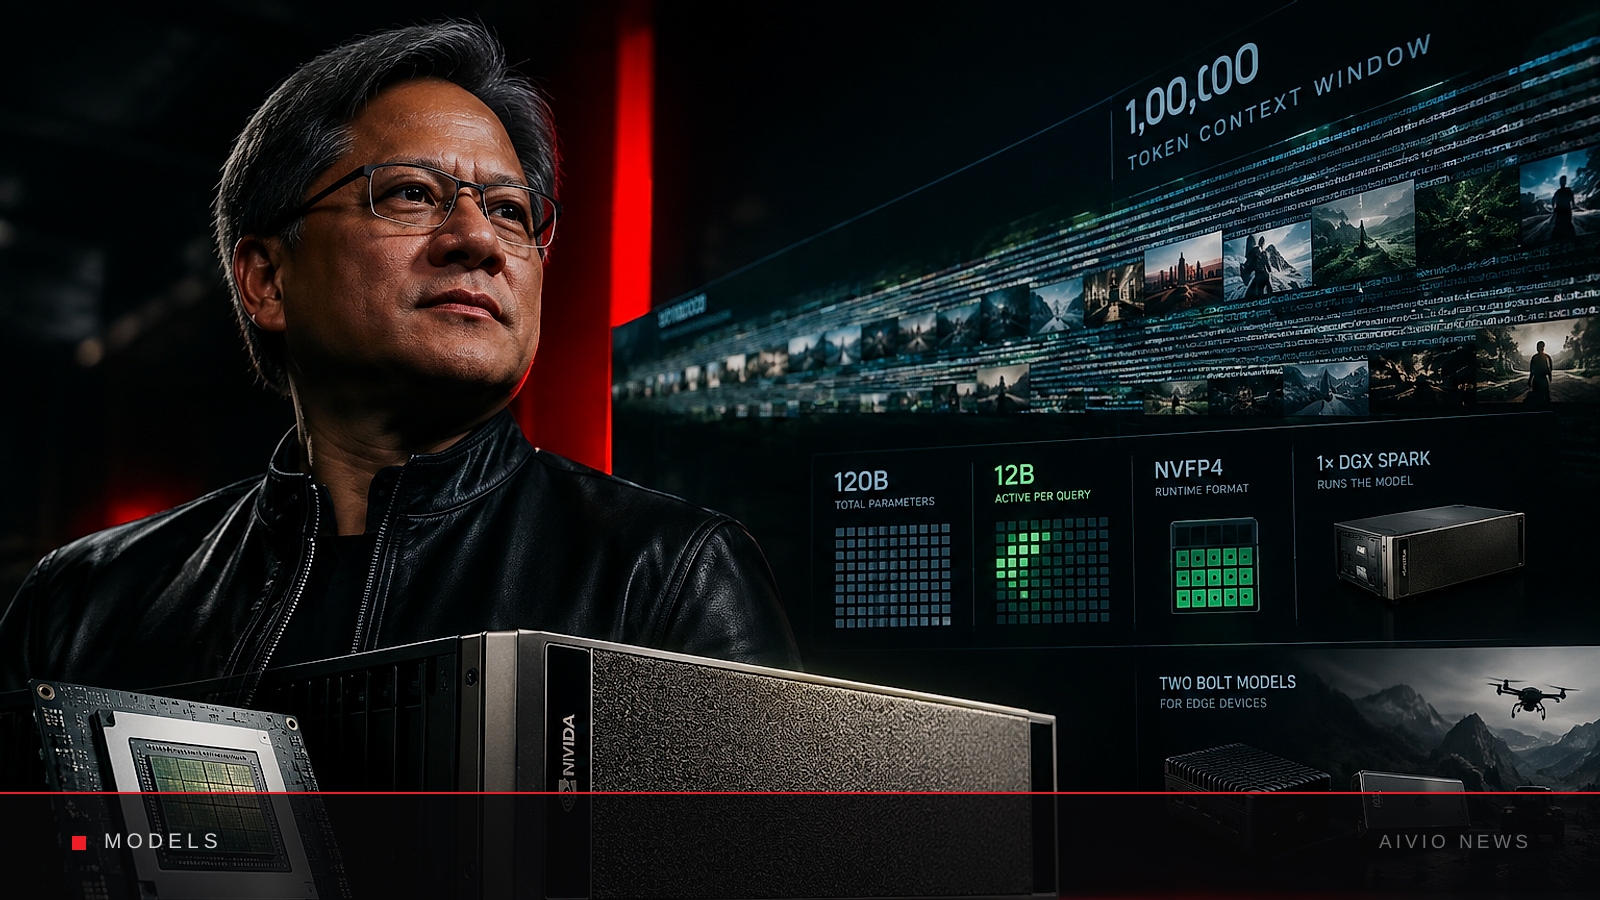
NVIDIA released Nemotron 3.5 Super VL, an open-weight multimodal model with 120 billion parameters, according to a report from MarkTechPost. The model combines text and image understanding in one system, which NVIDIA is presenting as a foundation for building AI agents, software that carries out multi-step tasks without constant human input.
Nemotron 3.5 Super VL uses a mixture-of-experts design, an architecture that splits a model’s parameters (the learned numeric values that store what it knows) across many smaller specialist networks and calls on only the ones a given input needs. NVIDIA says the model activates 12 billion of its 120 billion total parameters per query, which keeps the computing cost of each answer closer to that of a much smaller model while keeping the knowledge base of a far larger one.
The model also accepts up to 1 million tokens of context in a single prompt. Tokens are the small chunks of text or image data a model reads at once, and a 1-million-token window means Nemotron 3.5 Super VL can take in long documents, codebases, or sets of images without losing track of material from earlier in the same prompt. NVIDIA frames that capacity as useful for agentic applications, which often need to hold onto information across many steps of a task.
NVIDIA published the model’s weights, the trained numbers that define its behavior, in a format called NVFP4, a 4-bit numeric format that reduces the memory a model needs to run. According to the report, that reduction lets the full 120-billion-parameter model run on a single DGX Spark, NVIDIA’s compact desktop AI computer, instead of a rack of data-center hardware.
Alongside the main release, NVIDIA put out two smaller companion models called Bolt, built for edge devices, meaning computers that run AI models locally instead of sending requests to a remote server. The report did not give parameter counts, benchmark scores, pricing, or licensing terms for either the Bolt models or Nemotron 3.5 Super VL.
Those gaps are worth watching. A license determines how freely companies can build on an open-weight model, and benchmark results will show how Nemotron 3.5 Super VL’s performance compares with other open multimodal systems. Neither has been published yet, so judgments about the model’s real-world usefulness will have to wait for that data.
Sources
AI-generated · AIVIO News Desk